Repository navigation
[WIP] Ceph improvements - #147
weizhouapache wants to merge 97 commits into
Conversation


LibvirtStorageAdaptor#deletePhysicalDisk manually connected to Ceph via
librados/librbd to unprotect and remove every snapshot of an RBD image
before asking libvirt to delete the volume. libvirt's RBD storage
backend has supported VIR_STORAGE_VOL_DELETE_WITH_SNAPSHOTS since
1.2.20, which does the same unprotect/remove internally. Pass that
flag instead and drop the manual cleanup.

…pache#13835)

* kvm: fix RBD exclusive-lock leak that breaks revertSnapshot on Ceph

takeRbdVolumeSnapshotOfStoppedVm() called image.snapCreate(snapshotName)
twice. The first call creates the RBD snapshot, the second one always
throws RbdException ("Failed to create snapshot <uuid>") because the
snapshot already exists.

The duplicate is a merge artifact: 30d3066 ("Merge branch '4.20' into
4.22") resolved a conflict by keeping the call from both sides - each
parent had exactly one.

Because there was no finally block, that exception skipped rbd.close(image)
and r.ioCtxDestroy(io), so the agent kept the image open and held its RBD
exclusive-lock indefinitely. The exception is only logged, so the snapshot
job still reported success and the fault stayed invisible.

Consequences observed on a KVM + Ceph/RBD cluster:

- revertSnapshot fails with "com.ceph.rbd.RbdException: Failed to rollback
  snapshot <uuid>". librbd returns EROFS because a live peer holds the
  exclusive-lock; 'rbd snap rollback' only succeeds once that client dies
  and librbd can break the lock, which makes the failure look intermittent.
- getRbdSnapshotSize() is never reached, so every snapshot is reported with
  physical size 0 when snapshot.backup.to.secondary is false.
- The leaked watchers keep the image busy, so 'rbd rm' fails and the volume
  cannot be expunged - it stays stuck in state Destroy.

Note the method also runs for RUNNING VMs: createSnapshot() branches on
"RUNNING && !primaryPool.isExternalSnapshot()", and RBD is an
external-snapshot pool, so every RBD volume snapshot took this path.

Remove the duplicated call and move the image/IO-context cleanup into a
finally block so the lock is released even if the snapshot itself fails.

* kvm: release RBD handles on every path when cloning a volume from a snapshot

createRBDvolumeFromRBDSnapshot() closed the source image, the cloned image
and the RADOS IO context only on the success path, and called snapUnprotect()
only there too. Two paths escaped that cleanup:

- the early "Could not find snapshot ... on RBD" return, and
- any RadosException/RbdException from clone(), resize() or flatten(), which
  is caught and turned into a null disk.

Both leave the images open, so this client keeps the RBD exclusive-lock. That
later makes 'rbd snap rollback' (revertSnapshot) fail with EROFS from another
host, and keeps the image busy so 'rbd rm' cannot remove it - the volume then
stays stuck in state Destroy.

The failure paths after snapProtect() are worse: the snapshot stays protected,
and a protected snapshot can be deleted neither on its own nor together with
its volume.

Move the cleanup into a finally block, tracking whether the snapshot was
actually protected so it is unprotected exactly when it needs to be. Failures
during cleanup are logged and never mask the original outcome; a failed
snapUnprotect is logged at ERROR since it needs manual intervention.

This is the same class of defect as the leak fixed in
takeRbdVolumeSnapshotOfStoppedVm(); no behaviour changes on the success path.

* kvm: add regression tests for the RBD snapshot handle leak

Two tests around takeRbdVolumeSnapshotOfStoppedVm, using the MockedConstruction
pattern already used in this test class (the Rbd instance is created inside the
method under test, so it cannot be injected):

- createsSnapshotExactlyOnce guards the duplicated snapCreate call from coming
  back, and checks the image and IO context are released.
- releasesHandlesWhenSnapshotFails makes snapCreate throw and asserts the image
  is still closed and the IO context destroyed, so a future failure cannot leak
  the RBD exclusive-lock again.

takeRbdVolumeSnapshotOfStoppedVm, radosConnect and getRbdSnapshotSize widened
from private to protected so the test can stub the Ceph interactions.

* kvm: extract RBD handle teardown into null-safe helper methods

Address review feedback: the nested try-catch teardown blocks in the
finally clauses of takeRbdVolumeSnapshotOfStoppedVm and
createRBDvolumeFromRBDSnapshot are extracted into two reusable,
null-safe helpers that log but never throw:

- closeRbdImage (3 call sites)
- destroyRadosIoCtx (2 call sites)

No behavior change.

* kvm: extract RBD snapshot unprotect into a helper method

Follow-up to the teardown helpers: the snapUnprotect block in the
finally clause of createRBDvolumeFromRBDSnapshot moves into a
never-throwing unprotectRbdSnapshot helper, so the finally clause is
now free of inline try-catch constructions entirely.

No behavior change.

---------

Co-authored-by: calvix <7136358+calvix@users.noreply.github.com>

|
[SF] Trillian test result (tid-60)
|
|
[SF] Trillian test result (tid-61)
|

|
@blueorangutan package |
|
@weizhouapache a [SL] Jenkins job has been kicked to build packages. I'll keep you posted as I make progress. |

|
[SF] Trillian test result (tid-67)
|
|
@blueorangutan package |
the test failures (see below) with hostha have been fixed by kvm: support Host HA on Ceph RBD primary storage 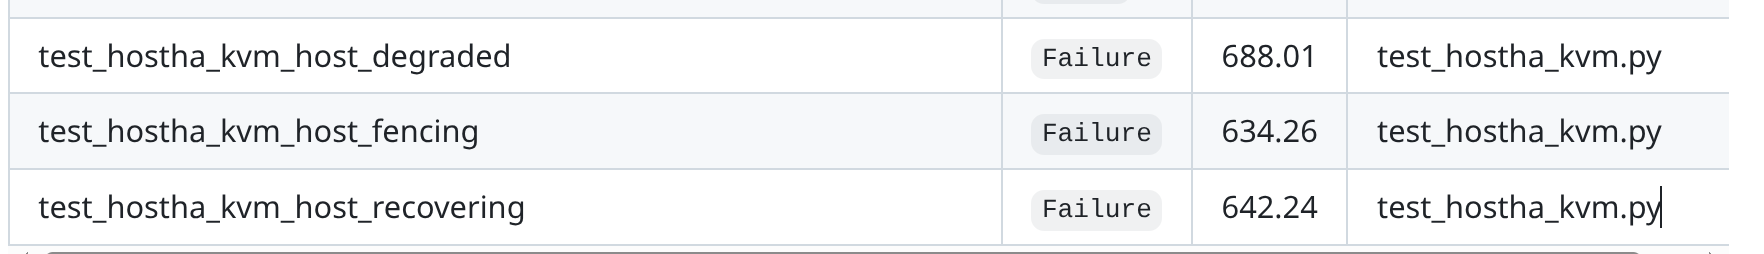
|
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19427 |
|
[SF] Trillian test result (tid-71)
|
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19454 |
|
[SF] Trillian test result (tid-78)
|
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19486 |
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19497 |
|
[SF] Trillian test result (tid-88)
|
|
[SF] Trillian test result (tid-89)
|


Restoring a volume from a backup and attaching it to a VM has been broken
since the restore commands were changed to run without a shell, in three
independent ways.

getDeviceToAttachDisk pipes virsh domblklist through awk, but passes the awk
program still wrapped in the single quotes a shell would have stripped. Run
directly, awk fails with "invalid char" and returns nothing, so the device
name is empty and charAt throws StringIndexOutOfBoundsException before any
attach is attempted. This affects every storage type. The exit value was also
never checked, and the output not trimmed, so even a working awk would leave
the trailing line separator and increment that instead of the device letter.

The RBD branch passes the literal string "<<EOF%sEOF" as a virsh argument. The
placeholder is never substituted with the disk XML, and a here-document cannot
work without a shell, so virsh is handed a bogus argument and fails. The XML is
now written to a temporary file that virsh reads.

The Linstor branch declares "--subdriver qcow2", inverting the previous
behaviour where Linstor got a raw attach and every other pool got qcow2. A
Linstor volume is a raw DRBD block device, so libvirt rejects it with "Image is
not in qcow2 format". The condition is restored, along with the "--driver qemu"
that was dropped.

…BD (apache#13991)

Ceph Tentacle 20.2.4 removed the legacy `auth_supported` librados option.
CloudStack builds RBD connection strings with `auth_supported=cephx`/`none`,
so every RBD operation through the KVM agent fails with
"failed to set RADOS option: auth_supported".

Switch the RBD string builder to `auth_client_required`, the modern option
used by the qemu rbd driver and accepted by current Ceph releases.

Co-authored-by: Wei Zhou <weizhou@apache.org>

… on RBD (apache#13361)

RBD erasure-coded pool support (apache#9808) added handling of the
rbd_default_data_pool storage-pool detail to RBDStringBuilder (qemu-img
path) and to createPhysicalDisk (blank volumes), but not to
createDiskFromTemplateOnRBD. As a result, ROOT volumes created from a
template via rados-java rbd.clone()/rbd.create() are created without a
data pool: all of their data objects land in the (replicated) metadata
pool instead of the erasure-coded data pool, defeating the point of EC
and consuming ~3x raw space.

Set rbd_default_data_pool on the Rados connection (before connect) in
both the same-cluster clone/copy branch and the cross-cluster copy
branch of createDiskFromTemplateOnRBD, using the destination pool's
detail. librbd then honors it as the default data pool when the new
image is created, so template-derived volumes get data_pool set, the
same way blank volumes already do.
…storeBackupCommandWrapper (apache#14006)

* kvm: detect mount failures and honour the configured timeouts on backup restore

Script.executeCommand returns null when the command fails, it does not throw,
so the try/catch around the mount and umount of the backup repository could
never fire and the return value was discarded. A repository that fails to mount
was therefore treated as mounted, and the restore carried on against an empty
directory until it failed later with a misleading "backup file not found". A
failed umount was ignored the same way, leaking the mount. Both now go through
executeCommandForExitValue and check the exit value.

The same refactor also dropped the timeouts. mountTimeout was still passed into
mountBackupDirectory but never used, and the rsync of the volume lost the
command timeout, so both fell back to the one hour default in Script instead of
the configured values. An unresponsive repository could hold a restore up for
an hour rather than failing after nas.backup.restore.mount.timeout seconds.

* kvm: clean up after a failed mount and bound the unmount of a backup repository

The directory created for the mount is removed by the caller in a finally block,
but that block is only reached once the mount has succeeded, so a repository
that cannot be mounted left an empty directory behind on every attempt. It is
now removed before the failure is reported, best effort and logged if it cannot
be.

The unmount ran without a timeout and so fell back to the one hour default in
Script. Unmounting a repository that has become unreachable blocks as easily as
mounting one, and this runs in the cleanup path of a restore, so it is now
bounded by the configured mount timeout like the mount itself.

* storage: enable RBD/Ceph volume encryption support (shared base)

Flip StoragePoolType.RBD from EncryptionSupport.Unsupported to Hypervisor so the
existing encryption control plane (allocator, endpoint selector, offerings) treats
RBD pools as encryption-capable.

The agent-side encrypted RBD create path is not implemented yet; it is delivered by
two follow-up tracks (qemu-native engine='qemu' and ceph-native engine='librbd').
Until then, fail closed at the two RBD create chokepoints in LibvirtStorageAdaptor
(createPhysicalDisk and createDiskFromTemplate) when a passphrase is present, so we
never silently produce a plaintext volume that the control plane believes is encrypted.

No change for existing unencrypted RBD volumes (guards only fire when a passphrase
is set; supportsEncryption() only affects volumes that require encryption).

* kvm: Ceph-native LUKS2 encryption for RBD volumes (engine='librbd')

Implements encrypted RBD data and root disks using librbd's native LUKS2
encryption, decrypted at runtime by libvirt/qemu via <encryption
engine='librbd'>. CloudStack manages the passphrase (existing model).

- RbdEncryption: isolated helper wrapping `rbd encryption format luks2`,
  cephx via --id + keyfile (secret not on the command line), LUKS passphrase
  via KeyFile. Kept separate so the CLI can later be swapped for a JNA binding
  (rados-java has no rbd_encryption_format API).
- LibvirtStorageAdaptor: create/clone the raw RBD image, then apply
  `rbd encryption format luks2`; mark the disk LUKS2 so encrypt_format
  propagates to the volume. Replaces the fail-closed guards.
- QemuObject.EncryptFormat: add LUKS2.
- LibvirtVMDef: render <encryption format='luks2' engine='librbd'>; the
  encrypt details now carry an optional engine.
- attach (KVMStorageProcessor) and boot (LibvirtComputingResource): set
  engine='librbd' for RBD-backed encrypted volumes.

NOTE: the CoW-clone-then-format path (encrypted root from an unencrypted
template) needs live-cluster validation for the parent-grow / usable-size
behaviour described in the Ceph image-encryption docs.

Builds: api + plugins/hypervisors/kvm (JDK11).

* kvm: gate host encryption probe on librbd support for RBD

hostSupportsVolumeEncryption() now advertises encryption capability if the
host supports EITHER qemu-native LUKS (qemu-img LUKS + cryptsetup) OR librbd
native encryption (rbd CLI with the encryption subcommand). Previously a
Ceph-only host that lacked cryptsetup would not advertise encryption even
though librbd can encrypt RBD volumes.

Split into hostSupportsQemuNativeVolumeEncryption() and
hostSupportsRbdVolumeEncryption(); kept HOST_VOLUME_ENCRYPTION as the single
host-wide flag (documented limitation: not per-pool).

* kvm: resize support for librbd-encrypted RBD volumes (#5)

Encrypted RBD volumes are encrypted natively by librbd and must be resized
with `rbd resize --encryption-passphrase-file` so librbd grows the encrypted
payload and keeps the LUKS header consistent. The existing encrypted-resize
path (resizeEncryptedQcowFile) uses qemu-img --object secret, which is for
qemu-native LUKS and does not fit the librbd LUKS2 layout.

- RbdEncryption.resize(): new `rbd resize` wrapper (cephx via --id + keyfile,
  passphrase via KeyFile, optional --allow-shrink).
- LibvirtResizeVolumeCommandWrapper: detect encrypted RBD and route to the rbd
  resize path, bypassing the libvirt v.resize and qemu-img paths.

Snapshot/revert, RBD<->RBD copy, and migration of encrypted RBD volumes need
no code changes: they operate on the raw (LUKS-containing) image at the block
level, and the destination passphrase secret is already created engine-agnostic
in LibvirtPrepareForMigrationCommandWrapper. These still require live validation.

Builds: plugins/hypervisors/kvm (JDK11).

* kvm: route online resize of encrypted RBD through virsh blockresize

For a running VM, an librbd-encrypted RBD volume must be resized in-band by
qemu/librbd, not out-of-band by the rbd CLI. Gate the CLI rbd-resize path on
!vmIsRunning so:
 - offline -> `rbd resize --encryption-passphrase-file` (librbd-aware), and
 - online  -> existing NOTIFYONLY path -> virsh blockresize, where qemu's
   block_resize delegates to librbd to grow the encrypted payload and notify
   the guest in one step (no passphrase needed; qemu holds the secret).

This avoids notify-less out-of-band growth and qemu/librbd size divergence
while the image is open. Online behaviour still needs live validation that
blockresize resizes the encrypted payload for engine='librbd' disks.

* kvm: encrypted RBD root disks (thin CoW clone + full-copy fallback)

Root disks could not be encrypted: cloning a plaintext template and then
`rbd encryption format`ing the clone leaves the inherited OS data unreadable
(the LUKS header offsets it), so the guest could not mount root.

Fix, in createDiskFromTemplateOnRBD, with two paths:
- Option A (same-cluster cached RBD template): grow the template base to
  reserve LUKS2 header space, snapshot+protect it (cloudstack-base-snap-luks),
  clone from it, apply the LUKS2 header, resize the clone to the requested
  size. Inherited template data stays readable through the clone's encryption
  and the clone is a thin CoW image (only the header is written).
- Option B (first-use / non-RBD template): create an empty image, apply a
  LUKS2 header, then import the template THROUGH the encryption layer via
  RbdEncryption.importTemplate (qemu-img convert -n into encrypt.key-secret).
  Correct but a full copy.

Validated end-to-end on Ubuntu 26.04 / libvirt 12.0.0: both boot; A is thin
(3.5 GiB provisioned, ~120 MiB used); LUKS2 verified at rest on Ceph.

* kvm: harden and align librbd-encrypted RBD volume code

Review pass over the librbd LUKS2 encryption feature to fix latent issues
and bring it in line with CloudStack conventions:

- RbdEncryption: reject empty/null passphrase with a clear error; round
  rbd --size up to MiB so a non-aligned request never shrinks the volume
  below what was asked for; create the temporary cephx conf/keyring 0600
  explicitly instead of relying on the umask.
- LibvirtStorageAdaptor: close Rados/IoCTX/RbdImage in a finally block on
  the encrypted-root paths (mirrors deleteVolume) so handles are not
  leaked on exceptions; use parameterized log messages instead of string
  concatenation; extract the encrypted-root Option A/B logic into
  createEncryptedRootCoWClone / createEncryptedRootFullCopy.
- RbdEncryption: use an instance logger (matching the plugin convention)
  and split argv construction into build{Format,Resize,Convert}Script so
  the generated commands can be unit-tested.

* kvm: add RbdEncryption unit tests

Assert the rbd/qemu-img argv built for format, resize and
convert-through-encryption (RBD and file sources), and that empty/null
passphrases are rejected. Command construction is verified without a
live Ceph cluster.

* kvm: refuse encrypted RBD hot-plug on libvirt < 10.1.0

libvirt 10.0.0 has an object apply-order bug (fixed in 10.1.0) that breaks
hot-plug of an encrypted rbd blockdev: on attach the disk is opened before its
LUKS secret object is defined, so the attach fails with "No secret with id
'...-format-encryption-secret0'". Booting a VM from an encrypted RBD disk is
unaffected (the QEMU command line resolves all -object before -blockdev).

Refuse the attach up front with a clear error (mirroring the existing
openvswitch/io_uring libvirt-version gates) instead of letting libvirt fail
opaquely. Only the RBD hot-plug path is gated; boot/root/detach are untouched.

* docs: add PendingReleaseNotes entry for librbd-encrypted RBD volumes

* kvm: route the encrypted RBD template import through QemuImg

RbdEncryption built its own 'qemu-img convert' command line, which
duplicated qemu-img knowledge outside of QemuImg. QemuImg could only
write to a plain filename destination, so importing a template through
the librbd encryption layer was not expressible with it.

QemuImg now supports a destination described by image options
(--target-image-opts, with -n implied since such a target always exists
already), exposed as convertIntoExistingTarget(). QemuImageOptions can
render its parameters under either image-opts flag.

RbdEncryption.importTemplate now composes QemuImageOptions and a
QemuObject secret and delegates to QemuImg; its hand-built convert
script is removed. The rbd CLI calls (encryption format, resize,
support probe) stay, as qemu-img cannot perform them.

No functional change to the generated command.

* kvm: use readable variable names in the encrypted RBD root helpers

Review feedback: single-letter and abbreviated names are hard to read.
Renamed in the two methods added by this PR only (renaming the rest of
the class is out of scope here): r -> radosConnection, io -> ioContext,
rbd -> rbdClient, base -> templateImage, s -> snapshotInfo, encSnap ->
luksReservedSnapshotName, haveEncSnap -> luksSnapshotExists, createSize
-> imageSizeWithLuksHeader, srcIsRbd -> sourceIsRbdPool.

No functional change.

* server, kvm: report and require RBD volume encryption separately

Review feedback: distinguish the two volume encryption mechanisms
instead of advertising them under one host flag.

host.volume.encryption goes back to meaning qemu-native LUKS only
(qemu-img LUKS + cryptsetup), as it did before this PR, and hosts now
additionally report host.volume.encryption.rbd for librbd encryption
(rbd encryption format).

The deployment planner requires the flag matching the pool type of each
encrypted volume - librbd for volumes on RBD pools, qemu-native for any
other pool type - at all three places it validated encryption support
before. The pool is taken from the pools proposed alongside the host
when present, so first deployments are matched accurately too; an
encrypted volume with no pool yet accepts either mechanism and the
storage pool allocator picks a pool the host can serve.

This also stops a host whose librbd is too old for 'rbd encryption
format' from being selected for encrypted RBD volumes; it previously
advertised encryption through the qemu stack and the VM failed to
start.

---------

Co-authored-by: Václav Rozsypálek <vaclav.rozsypalek@master.cz>
Co-authored-by: calvix <7136358+calvix@users.noreply.github.com>
findByID will fail for dummy template as it is stored in the deleted state.
…ion (apache#14162)

* kvm: allow importVm importsource=shared from an RBD pool

The CheckVolumeCommand wrapper on the KVM agent only accepted file based
pools, so importing a root disk straight from Ceph failed on the agent
with "Unsupported Storage Pool" and surfaced as "Disk not found or is
invalid" on the management server. Add RBD to the supported pool types,
take the virtual size from the disk libvirt resolved (qemu-img cannot
open a bare RBD image name), skip the QCOW2 header check for raw RBD
images, and build the rbd: URI when running qemu-img info, the same way
LibvirtGetVolumesOnStorageCommandWrapper already does for
listVolumesForImport.

* kvm: record the real image format on an imported volume

importVolume and updateImportedVolume both stamped the cluster default
format for the hypervisor, so a volume imported from an RBD pool was
recorded as QCOW2 while a natively deployed volume on the same pool is
RAW. This affected both entry points: importVm importsource=shared for a
root disk, and importVolume for a data disk.

Pass the format the hypervisor reported for the existing image, from the
check answer for a root disk and from the volume listed on the pool for
a data disk, and fall back to the hypervisor default only when no format
is reported. This also corrects a raw image imported from a file based
pool.

* vm import: plan the instance inside the pod and cluster of the requested pool

importKVMInstanceFromDiskImage planned with the pod and cluster unset, so
the planner was free to pick any host in the zone by capacity. When it
picked a host in a cluster that cannot see the pool the caller named, the
volume check ran against whichever pool that cluster does have, and the
import failed with "Disk not found or is invalid" although the image was
fine.

Take the pod and cluster from the pool the caller passed, the same way
importVolume already derives its host from the pool's scope

* verify qemu is able to read the rbd image since check can not be done on a raw file

* use computed volumeDetails in success path as well.

* ui: do not call the imported disk a QCOW2 image

The import wizard for local and shared storage described the disk as a
QCOW2 image. An image on an RBD pool is raw, and a raw image on a file
based pool can be imported as well, so the wording is wrong for both.
Call it a disk image instead.

Only the English strings are changed; the other locales come from
Transifex.
apache#14188)

getPhysicalDisk() asks libvirt for the volume. A volume that was just
created by the management server is not in this host's libvirt pool
cache, so the lookup misses and getVolume() falls back to refreshing the
whole pool. Refreshing an RBD pool opens and stats every image in it, so
the cost grows with the number of volumes in the pool and is paid on
every VM start. On a pool holding 950 images that is 11.7 seconds added
to each start, against 0.005 seconds to list the image names.

Look RBD volumes up directly through librbd instead. Creating, cloning,
resizing, copying and deleting RBD volumes in this class already use
librbd directly; only the lookup went through libvirt.

Because this runs on every VM start, the connection is handled more
carefully than at the existing call sites:

 - the rados connection is shut down in a finally, so a client is not
   left for the finalizer. KVMStoragePoolManager.getPhysicalDisk retries
   a missing volume 100 times, so leaking here would mean 101 live
   librados clients for one absent volume.
 - the image is opened read only, since it is only stat'ed, and so
   cannot take the exclusive lock.
 - the image is closed through a helper that does not throw, so a failed
   close cannot discard a successful lookup or hide the original error.
 - the cephx key is only set when the pool has a user. librados aborts
   the process if it is handed a null value.
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19792 |
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19794 |
|
[SF] Trillian test result (tid-160)
|
Assert that the encryption format and passphrase secret lists of TestVolumeEncryption are not empty, instead of asserting they are not None, which findall() never returns. Compare the storage pool type case-insensitively, give the direct download test a unique storage tag, skip the live VM migration test for every RBD source pool, and drop an unused variable in test_list_storage_pools.

cba8b2d to
c21efaf
Compare
…e test PRs

Add the commits for apache#14386, apache#14320 and apache#11931 and update the notes.
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19853 |
|
[SF] Trillian test result (tid-169)
|
Fixes apache#12002.

On Ceph/RBD primary storage, deleting a volume also destroys any of its
remaining snapshots: LibvirtStorageAdaptor#deleteVol passes
VIR_STORAGE_VOL_DELETE_WITH_SNAPSHOTS for RBD pools, so libvirt
unprotects and removes them along with the image.

Run that same snapshots cleanup earlier: for a KVM + RBD volume, delete
its primary-only snapshots before sending the volume delete command,
while they can still be found and removed cleanly. This is the choke
point shared by both the standalone DeleteVolume API and VM
destroy/expunge, so it covers both affected flows. The existing
post-delete cleanup in deleteVolumeCallback stays in place as a no-op
safety net for anything this pass didn't find.

Verified live on a KVM + Ceph environment (RBD primary storage,
snapshot.backup.to.secondary=false): destroying a VM with a
primary-only snapshot now deletes it cleanly.
- Report "cannot tell" instead of dead when the RADOS heartbeat object is
  missing or malformed, or when the neighbour monitors no HA pool
- Decide the verdict over all pools instead of the last one
- Keep the HA monitor thread alive when a pool cannot run its heartbeat
- Do not monitor an RBD pool whose Ceph Python bindings are missing
- Share the heartbeat freshness rule (interval plus slack) between scripts
- Keep deleting RBD and SharedMountPoint pools with their details
- Move the RBD specific decisions into the storage pool
|
@blueorangutan package |
|
@weizhouapache a [SL] Jenkins job has been kicked to build packages. I'll keep you posted as I make progress. |
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19947 |
|
@blueorangutan package |
|
@weizhouapache a [SL] Jenkins job has been kicked to build packages. I'll keep you posted as I make progress. |
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19951 |
|
Packaging result [SF]: ✔️ el8 ✔️ el9 ✔️ el10 ✔️ debian ✔️ suse15. SL-JID 19956 |
…ed (PR 14623)

Cherry-pick of the PR apache#14623 changes to the resize path, applied on
4.23.0-ceph. The VM snapshot XML tests from the PR are left out since
they are not on this branch.
test_08_resize_volume and test_12_resize_volume_with_only_size_parameter
now also grow the VM's ROOT volume by one GB and check the new size, so
ROOT volume resize is covered on any primary storage type.

The helper resize_root_volume leaves the VM running.
The encrypted RBD hot-plug error and the openvswitch requirement error printed the raw number of the libvirt version, such as 10000000, instead of 10.0.0. Format it with LibvirtComputingResource.prettyVersion, which is now public and static.
…older than 10.1.0

libvirt before 10.1.0 applies the LUKS secret of an encrypted RBD image to a running domain after the image, so the block copy into it fails. Refuse it before anything is created on the destination pool, with the libvirt version needed and the one detected, as the hot-plug of an encrypted RBD volume does.
When the host refuses or fails the restore, the NAS provider returned only false and the backup manager answered with the generic error, so the reason the host gave, such as an RBD image carrying snapshots the backup path did not take, never reached the user. Throw a BackupProviderException with the details of the answer, which the backup manager hands to the user as it is.
…rom a backup

Restoring an RBD volume from a backup rewinds the image wholesale, which removes every snapshot it carries, so the host refuses it when the image carries a snapshot the backup path did not take. Check the volume snapshots kept on primary storage in the management server first, and refuse before anything is sent to the host with the names of the volume and of its snapshots. The host still checks the image, which also catches snapshots CloudStack does not know about.
Only the removal from the HA monitor depends on the pool types with HA
support. The delete itself stays as it was: only NFS uses the delete
without the details, which unmounts the pool. The other types keep the
delete which takes the details, so that the libvirt pool, which VMs may
still use, is not destroyed.
…ts take

A write of the heartbeat which starts on time can take long when Ceph is
slow: connecting and writing take up to 30 seconds each. The agent stops
a write after heartbeat.update.timeout, so a heartbeat of a host which is
alive can be older than the interval by that time.

The agent gives heartbeat.update.timeout to the heartbeat and the VM
activity scripts of RBD with -w, and a heartbeat is stale when it is
older than the interval plus that time. Without -w the scripts use
60 seconds, the default of the property.
…e others

A host which can not tell whether the heartbeat of another host is on
going, e.g. because it monitors no storage pool or Ceph can not be
reached from it, answered that the heart is beating. The management
server returned on the first such answer, so one such host kept the
others from deciding that a host is down.

The pool check of RBD returns null when the script can not tell, and
KVMHAChecker combines the pools: alive if one is alive, dead if the
ones which can tell are dead (or one is dead and that is reported), else
not told. CheckOnHostCommand then answers with determined=false, and
KVMHostActivityChecker skips such an answer and asks the next neighbour.
… HA and RBD resize PRs

Add rows 71 to 81, add PR 14623, and say which commits are on the PR branches.
930ba10 to
81c4481
Compare
|
[SF] Trillian test result (tid-196)
|


Description
This PR is used to test several ceph changes, which includes
Bug fixes
The commits of this branch are mapped to their apache/cloudstack pull requests in commit-pr-map.md.
Types of changes
Feature/Enhancement Scale or Bug Severity
Feature/Enhancement Scale
Bug Severity
Screenshots (if appropriate):
How Has This Been Tested?
How did you try to break this feature and the system with this change?